OpenAI will merge ChatGPT and Codex into one allowance measured in tokens for Plus, Pro and Business plans starting in December. Instant chat stays outside the meter, combined balances will show in Settings, and OpenAI has not published allowance sizes or an exact start date.
OpenAI is ending the split that kept your chats and your coding in separate pots. From December, a heavy Codex run and a long session with an advanced model in ChatGPT will draw on the same allowance for Plus, Pro and Business subscribers.
The change matters most for people who use both products hard in the same day. Work that cost nothing against Codex until now will cost against it from December, unless that work stays in Instant chat.
The Announcement
OpenAI set out the change in a Help Center article titled Understanding ChatGPT and Codex usage limits. The article gives the reason in one line, and it is about product shape as much as billing.
“Starting in December, Plus, Pro, and Business plans’ usage allowance will be shared across ChatGPT and Codex as we bring the agentic capabilities of Work into the main ChatGPT experience.”
Usage will be measured in tokens, which OpenAI defines as the units of information a model processes and generates. How much of the allowance a request uses will depend on the model chosen and the task asked for, and the article says more advanced models and complex tasks generally use more of the allowance.
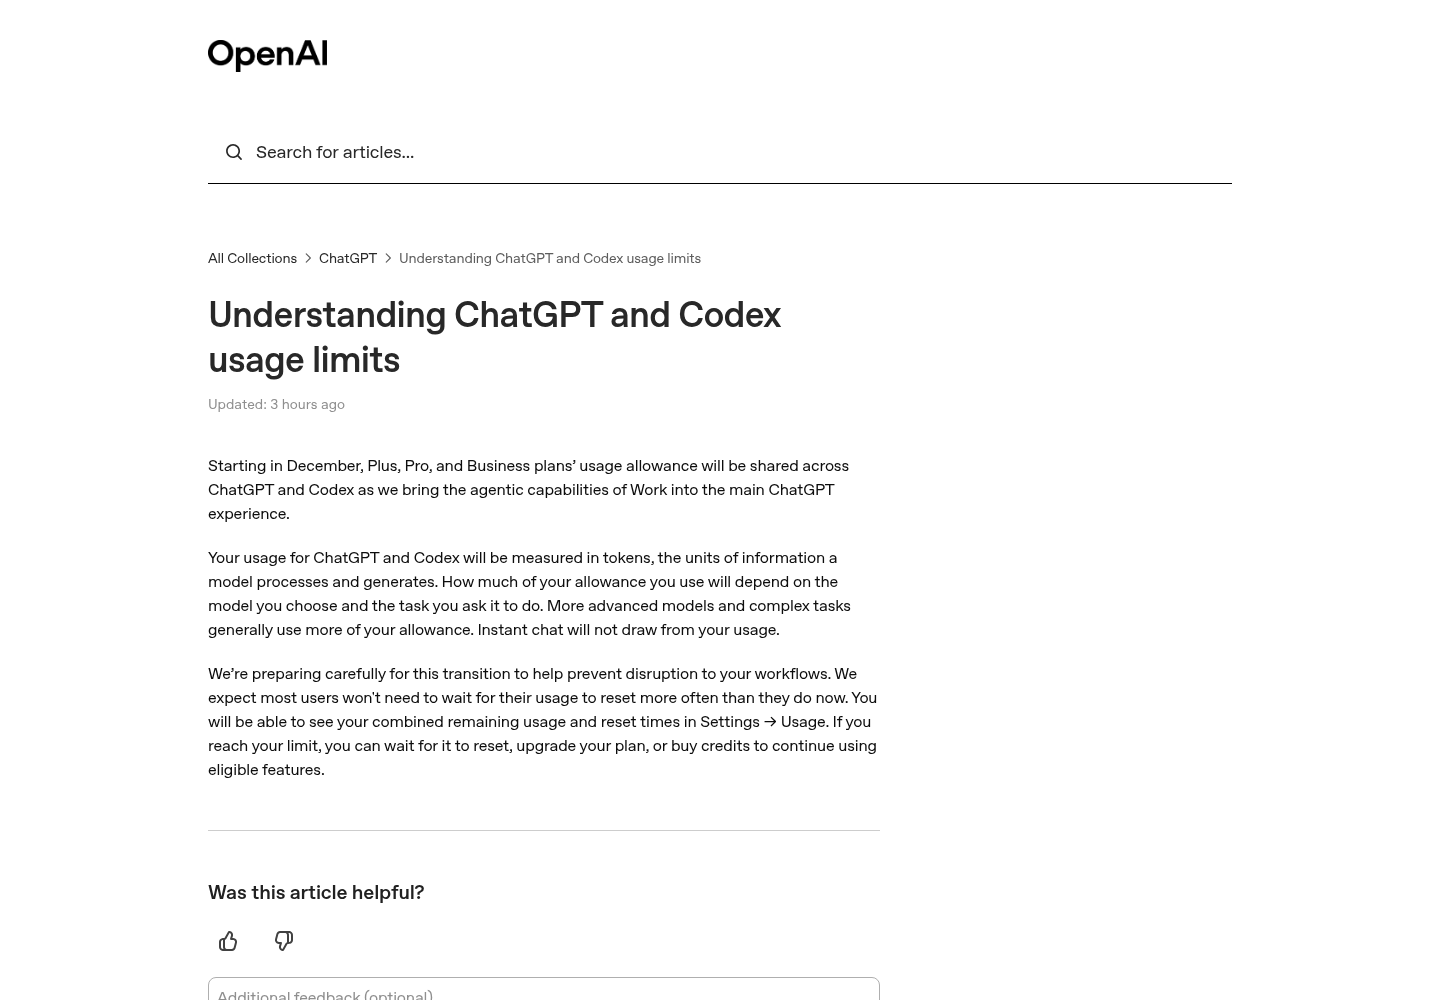
One exception is named plainly. Instant chat will not draw from your usage, so quick questions on Instant stay outside the shared pool. Everything else in ChatGPT and Codex sits inside it.
Subscribers will see combined remaining usage and reset times in Settings, then Usage. If the limit is reached, OpenAI lists three options: wait for it to reset, upgrade your plan, or buy credits to continue using eligible features.
What Already Shares, and What Joins in December
Part of this pool already exists. In its guide to using Codex with a ChatGPT plan, OpenAI says Codex, ChatGPT Work, ChatGPT for Excel and Workspace Agents use a shared allowance and credit pool when those features are available on your plan. Usage there depends on the model, where the task runs, task complexity, context, reasoning, speed and tools, and a long running task can use substantially more than a short request.
Ordinary chats have run on separate limits until now, as coverage of the Help Center change explains. December brings those chats into the pool, with Instant as the only stated carve out. Readers who juggle several coding agents, as in our guide to running Claude Code, Codex and Opencode together, will feel that join most directly in Codex.
OpenAI says it is preparing carefully for the transition to help prevent disruption to workflows. It also says it expects most users will not need to wait for their usage to reset more often than they do now. That second line is a company expectation, not a guarantee, and it arrives with no allowance figures to test it against.
Important Details
| Item | Detail |
|---|---|
| Plans named | Plus, Pro and Business |
| Start | December, with no exact date given |
| What is shared | One usage allowance across ChatGPT and Codex |
| Unit | Tokens, the units a model processes and generates |
| What costs more | More advanced models and complex tasks, generally |
| What is exempt | Instant chat |
| Where to check | Settings, then Usage, for combined remaining usage and reset times |
| At the limit | Wait for the reset, upgrade the plan, or buy credits for eligible features |
| Allowance sizes | Not published for any plan |
| Other plans | Free, Go, Enterprise and Edu are not mentioned in the announcement article |
The missing numbers are the story inside the story. Without a token allowance for each plan, no subscriber can compare the new pool with the two budgets it replaces, and no team can plan December capacity from the announcement alone.
Context from the days before the notice cuts both ways. Coverage by Mad Robot reports that OpenAI cancelled a planned cut to the Pro 200 Work and Codex allowance at the end of October, a cut that would have taken it from 20 times to 10 times the Plus allowance, and doubled the Pro 100 and Pro 500 allowances instead. Those moves are reported context, not part of the December article itself, and OpenAI has not said how they map onto the new shared pool.
Why Model Choice Will Matter More
OpenAI already publishes estimates that show how wide the spread between models can be. On its Codex pricing page, the current estimates for local messages in a five hour window on Plus range from 5 to 45 with GPT-6 Astra to 350 to 3000 with GPT-6 Luna. The page stresses that these are estimates, not fixed message limits, that cloud tasks may use more of the allowance than local messages, and that weekly limits may also apply.
Current Plus estimates for local Codex messages in a five hour window
Source: OpenAI Codex pricing page, checked November 2, 2026. Bars use the upper end of each published range. These are current Work and Codex estimates, not December allowance figures.
That spread is why a token meter changes behaviour. A routine task run on a light model and a hard task run on an advanced model will no longer land in separate worlds once chat joins the same pool. Pro plans currently have no five hour limit in Work and Codex on the pricing page, but the December article does not say whether that arrangement stays, changes, or gains a new shape.
What’s Next
Confirmed steps are narrow. The shared allowance starts at some point in December for the three named plans, combined balances will appear in Settings, then Usage, and the three options at the limit are wait, upgrade or buy credits. Nothing else in the article is dated or sized.
Open questions are material, and they should stay labelled as open. OpenAI has not published an exact start date, token allowances by plan, or any statement on whether current windows and per model caps in chat stay alongside the pool or are replaced by it. It has also not said, in this article, how the Business pool is counted for each member against a workspace as a whole.
Reporting on the notice adds two smaller signals, both unverified as policy. Subscribers on Hacker News say OpenAI emailed the change under headings about Chat and Work coming together, as Mad Robot reported, and that reporting found no blog post or statement beyond the Help Center page. Treat both as reported colour until OpenAI publishes more, not as confirmed rollout detail.
For subscribers, the practical move in November is measurement. Check Settings, then Usage, note how chat and Codex use split across a normal week, and move everyday questions to Instant where Instant is good enough. When December numbers land, that record is the only honest basis for judging whether the single pool is generous, tight, or about the same.
Sources
- OpenAI Help Center: Understanding ChatGPT and Codex usage limits
- OpenAI Help Center: Using Codex with your ChatGPT plan
- OpenAI: Codex pricing page
- Mad Robot: ChatGPT and Codex will share one usage limit from December
- Screenshot: OpenAI Help Center
- Body image: Dirty Static house style illustration
END OF TRANSMISSION
Stay curious. Question everything.