NVIDIA used today to load RTX Spark with software: a speech model that tops the open leaderboard, Liquid AI models with day one support, a GPU slider that settles fights between your game and your agents, and a launch night game with path traced Minecraft behind it.
When we compared the RTX Spark laptops, the verdict was split down the middle: brilliant at local AI, beaten at games, with the software story still being written. Today NVIDIA shipped a stack of that software in one drop: new open models, a control for sharing the GPU between apps and agents, and fresh games. It reads like a direct answer to the review, so here is what actually landed.
A speech model that tops the open chart
The headline release is Nemotron 3.5 Transcribe, an open weight speech model NVIDIA introduced today. One model does the work that used to take three: it transcribes a recording, labels who is speaking, translates, and answers questions about the audio, all steered by plain language prompts. Ask it to list the decisions made in a meeting and it will try. It covers 40 languages, including seven Indic languages, and ships today on Hugging Face in BF16, FP8, and NVFP4 formats.
By NVIDIA’s count, it ranks first on the Hugging Face Open ASR leaderboard and second among open weight models on Artificial Analysis, with about 4.3 billion active parameters, roughly 80 percent fewer than the model it chases. Treat leaderboard claims the way you treat any vendor claim, but the shape of the thing is the story: transcription this capable, small enough to run on a laptop, with the weights open and the audio never leaving your machine. It runs on RTX Spark, DGX Spark, and Jetson AGX Thor.
The GPU truce
The most original item in the drop is a slider. RTX Spark machines are built to run agents in the background while you work or play in the foreground, and both sides want the same GPU. The NVIDIA App now has resource management controls that let you choose the split: favour the app in front of you for full performance, or feed the agent behind it so the work finishes sooner. The control lives under System, then Advanced, and it needs hardware accelerated GPU scheduling switched on in Windows Settings.
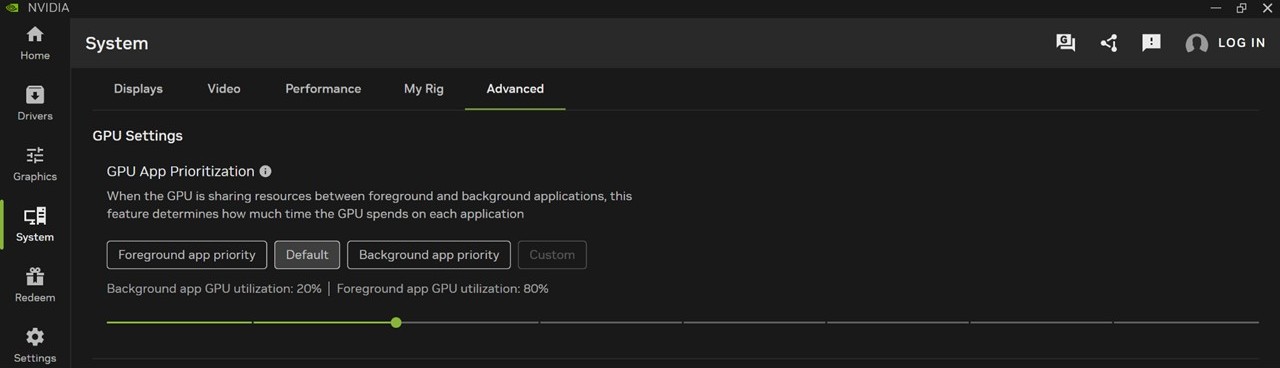 The referee in person: GPU App Prioritization, under System then Advanced, shown favouring the app in front. Image: NVIDIA
This sounds small and it is not. Every machine that runs local agents hits this fight within a week. A platform that admits the fight exists and hands you the referee controls is a platform that expects agents to be permanent residents, not demos.
Liquid models and the local agent stack
Liquid AI’s LFM3 family arrives with day one support. The family spans text, vision, audio, and decision models on one shared backbone, all open weights, and NVIDIA notes the new 1.7 billion parameter base model outperforms the family’s previous 2.6 billion parameter base. The suggested work is agent work: triage an inbox, manage a calendar, read documents and screens, transcribe and translate speech, route support tickets. NVIDIA names Hermes Agent, Pi, and OpenClaw as the harnesses, which puts our Hermes setup guide squarely in this machine’s intended workflow. The models run through llama.cpp and vLLM, and you can fine tune them on the laptop itself.
The supporting cast matters too. Nemotron 3.5 Bolt E4B is out in a build that holds conversations and runs multistep agent tasks in as little as 4GB of memory, with a 74B class sibling tuned for heavier agent loads on RTX Spark’s big unified pool. Black Forest Labs’ FLUX 3 Image Klein, a 5.6 billion parameter open weights image model, runs in NVIDIA optimised builds with as little as 8GB of VRAM. At the GTC Berlin keynote, agents on an RTX Spark machine even helped teach Hugging Face’s Microduck robot to walk, planning the course while Isaac Lab trained the policy. The laptop is being positioned as the desk sized end of the whole robot pipeline.
Games answer back
The games half of our verdict gets its own rebuttal. Phantom Blade Zero launches tonight, October 28, at 7 p.m. PT on Steam and the Epic Games Store, with ray tracing and DLSS Dynamic Multi Frame Generation good for up to 6x frame generation by NVIDIA’s measure. RTX Remix 1.6, out last week, brings path traced Minecraft Java Edition into the fold and adds DLSS 5 with 3D Guided Neural Rendering, native RTX Spark support, and agent assisted modding workflows; Portal with RTX and the Half-Life 2 RTX demo pick up the same upgrades starting today. Photoshop and Premiere now offer native RTX Spark support in beta for the creator side of the ledger.
The Phantom Blade Zero trailer, straight from NVIDIA’s announcement post. Video: NVIDIA and S-GAMEThe shape of the platform
Underneath the announcements, the hardware pitch is unchanged: a Blackwell RTX GPU and a Grace CPU on one superchip, up to 128GB of unified memory and up to a petaflop of FP4 AI performance, in laptops as thin as 14mm and as light as three pounds, from ASUS, Dell, HP, Lenovo, Microsoft, and MSI, starting at $2,599 with the 128GB builds on shelves. A 64GB DGX Spark desktop joins the line for people who want the same stack without the screen.
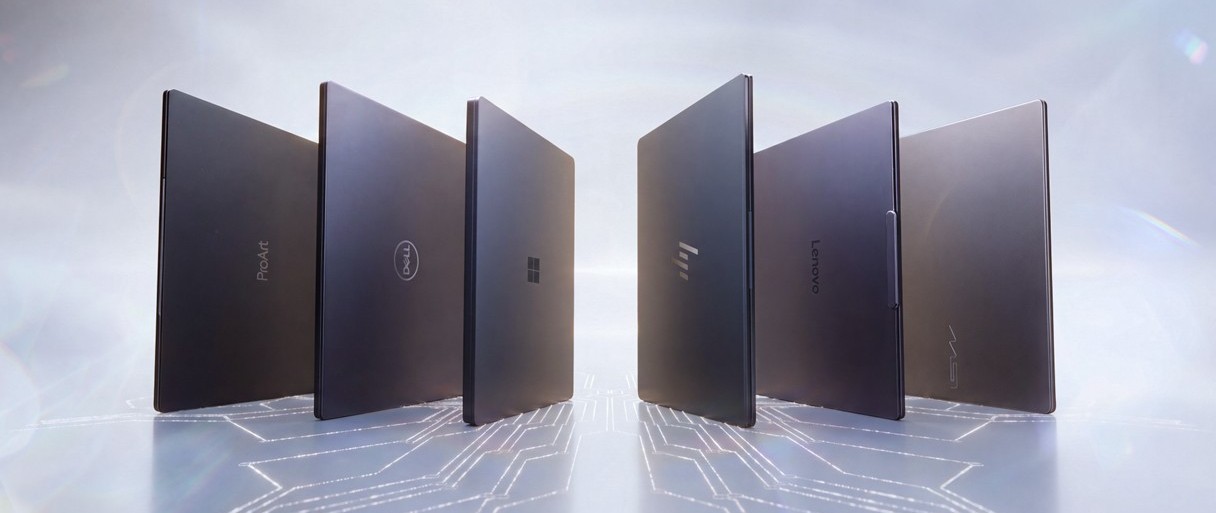 The RTX Spark range: six makers, one superchip. Image: NVIDIA
Software was always the open question on RTX Spark, and questions like that are answered by cadence, not keynotes. One drop does not settle it. But a top ranked open speech model, a credible small model family, an honest control for the app versus agent fight, and games arriving on schedule is what the beginning of an answer looks like. We will be watching for the second drop.
Sources
- The full announcement: NVIDIA Blog
- Our comparison of the machines: RTX Spark Laptops Compared
- Screenshots and trailer: NVIDIA
- Nemotron 3.5 Transcribe: Hugging Face
END OF TRANSMISSION
Stay curious. Question everything.